Technical report: Robota-Embed: Unified VLA Embeddings for Robot In-Context Learning and Evolution

Yunze Liu1,*, Jing Wang1,*, Shenrui Wu3, Wenkun He2, Guanqi Zhan1, Xianzheng Ma4, Junyu Chen1, Wenhang Ge1, Haozhan Tang5, Yuchao Gu1, Zhuoyang Zhang2, Zekai Wang3, Dantong Niu3, Zhen Dong1, Yuke Zhu1, Trevor Darrell3, Linxi “Jim” Fan1, Song Han2, Han Cai1,†
1NVIDIA 2MIT 3UCB 4Oxford 5CMU *Equal contribution †Corresponding author

01 · Overview

A robot should retrieve the right future.

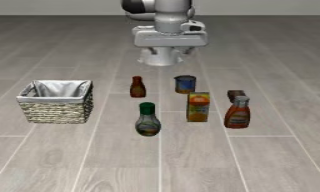
Robotic experience is abundant, but the useful context is not simply a visually similar frame. It is an interaction whose future matches what the robot is doing now.

Recorded EgoDex human interactionHumanRecorded DROID robot interactionRobotRecorded LIBERO simulation interactionSimulation
Vision
“Pick up the bbq sauce and place it in the basket.”
Language
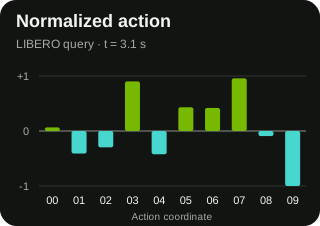
Actual normalized ten-coordinate LIBERO query action at 3.1 secondsNative action
Robota-Embed
One joint VLA embedding
Embed2EvolveSuccess ↑ · tokens ↓
Develop memoryFreeze and test
Memory↔HarnessGPT-6 Astra
ManiSkill · Direct24%→68%
Tokens / rollout · Direct0.921M→0.518M
Embed2ICLSuccess rate ↑
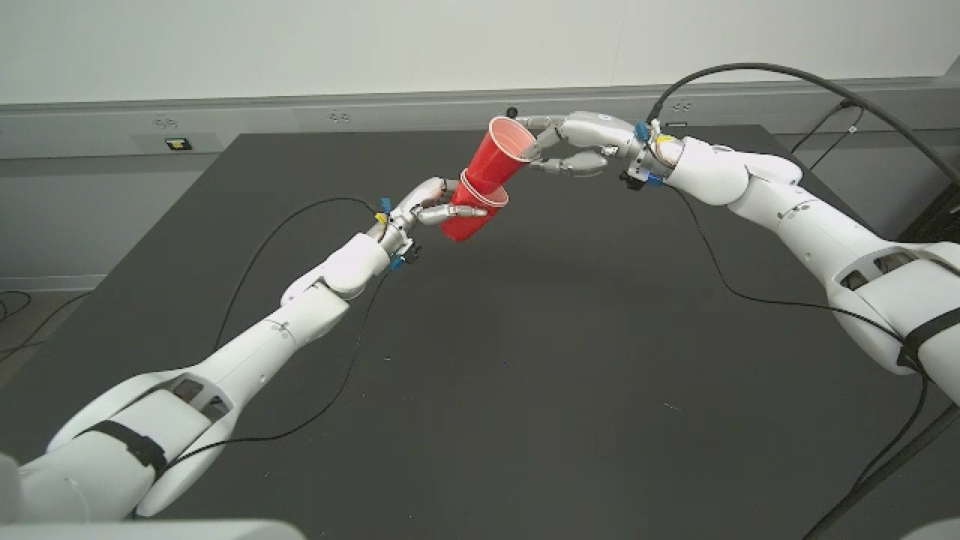
Recorded training-free DROID reference from the paperDROID referenceRecorded Fast-WAM Split Cup real-robot execution from the paperReal-robot execution
Training-freeDROID-SimNo warm-up 47.0% → 56.3%
Training-basedLIBERO difficult subsetOfficial release 86.4% → 92.8%
Modality contributionfour-domain average clip R@1 (%) ↑
VLA47.3VL20.1VA7.1LA23.0
Robota-Embed-Benchfour-domain average R@1 (%) ↑
Clip-levelCLIP ViT-L/14 1.2Gemini Embedding 2 25.2Ours 47.3
Episode-levelCLIP ViT-L/14 3.2Gemini Embedding 2 48.3Ours 81.8
Embed2Evolve efficiency vs. Direct
Shared successesPolicy decisions ↓ 64.1%Shared successesObserved client time ↓ 41.4%All test rolloutsPolicy tokens ↓ 43.7%All test rolloutsReference cost ↓ 41.8%
01
Observe the interaction

Encode the current interaction crop or frame, instruction, and native action.

02
Retrieve a relevant future

Search a shared gallery for experience whose continuation fits the current interaction.

03
Turn experience into context

Grow task-local memory across attempts, or use retrieved experience as policy context.

02 · Robota-Embed

Vision, language, and action.
One predictive retrieval space.

Robota-Embed represents a current interaction and a recorded future continuation with normalized embeddings, while retaining each data source's native action interface.
Inside a retrieval

Retrieve a useful continuation from real robot experience.

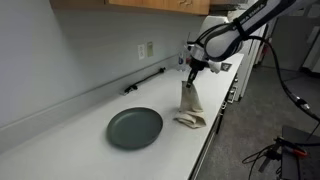
DROID · recorded example

Current interaction t = 16 s

DROID current interaction before unfolding the clothOriginal frameRecorded DROID query cropRobota-Embed crop
“Unfold the cloth on the counter.”
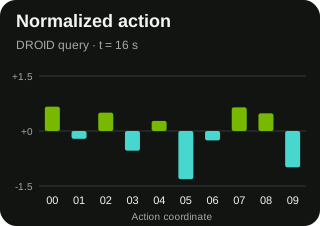
Actual normalized query action, all ten coordinates plotted on a common signed scale Recorded action values ↗
V · L · ARobota-EmbedCosine retrieval
Useful contextRecorded continuation · 4 s
Compare DROID retrieval results ↗
01

Predictive alignment

Match a current interaction state to a future continuation rather than pairing static views of the same instant.

02

Action-native retrieval

Treat native actions as retrieval evidence alongside vision and language, preserving what the robot is physically doing.

03

Shared heterogeneous space

Map source-specific action formats through dedicated projectors into one normalized embedding space.
Inside Robota-EmbedArchitecture & training objectivesShared VLA space · three objective groups
Current queryat t
EgoDex current frame used in the original objective figureCurrent frameCorresponding recorded SAM3 cropSAM3 crop
Instruction
→PdAction
Future targetNext 4 s
Early frame of the recorded paired EgoDex futureLater frame of the same recorded futureFuture video · 16 frames / 4 s
Same text
→PdActions · native rate
Shared VLA Transformershared θ + video tokenizer
Query lane
Query adapter Aqshared θTarget adapter Ak
Target lane
Embedding headShared projection
Time meanLN + LinearL2q
Time meanLN + LinearL2k
one L2-normalized 1024-D vector per endpoint
Cosine similaritycos(q, k)
ℒalignPredictive retrieval alignment
q⇄kbidirectional
Future clips
Queries
PairedNegativeIgnored
ℒgroundMultimodal grounding and discrimination
Modality swaps
LVA→ s(q, k+)
margin m
LVA′→ s(q′, k+)
one query modality changes; the paired target k+ stays fixed
Hard negatives
q
class-wise maximum-cosine task/object/action negatives after validity masking
ℒregRepresentation regularization
Center + spread
→
illustrative direction: near-zero centers, non-collapsed variance and effective rank
Data preparationMulti-source training corpus1,695,684 accepted pairs · four sources
Multi-source episodesEgoDexDROIDLIBERORoboMIND–Franka-dual
Split by episode
01Dense anchors
Current tFuture 4 s
Dense time anchors
02Object localizationRecorded source image and localization from the paper's curation exampleTask phrase → SAM3
03Object zoomActual object crop from the same curation example320 × 192 crop
04Quality gateQwen3-VL
VisibleTask-relevantSeparableUnoccluded
05Predictive pair
Current querytext · image · actionFuture targettext · video · action
Accepted anchor-level pairs1,695,684
Episodes are split before dense anchoring. Filtering uses only the instruction and current observations; each accepted within-source anchor is paired with the strictly future 4 s, comprising 16 video frames and native-rate actions. Sources are sampled equally during training.

03 · Robota-Embed-Bench

Evaluate every source in one gallery.

Robota-Embed-Bench combines human, simulated, and real-robot experience while preserving a single retrieval protocol.

4000queries
8000gallery entries
47.33%four-domain average clip R@1
81.77%four-domain average episode R@1
Evaluation protocolFour sources, one shared galleryExact clips and episode identity are scored separately

Robota-Embed-Bench

Four sources, one shared gallery.

The evaluation contains 3,200 source-scoped query episodes and an 8,000-window gallery manifest. Exact clip positives and episode-level alternatives are evaluated separately.
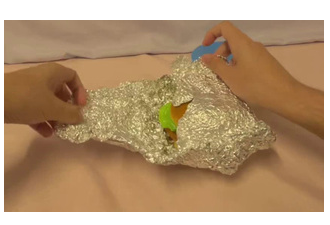
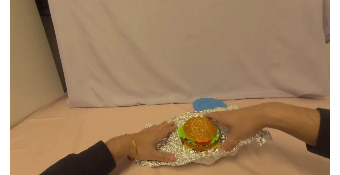
EgoDexDROIDLIBERORoboMIND–Franka-dual
EgoDexHuman experience foundation
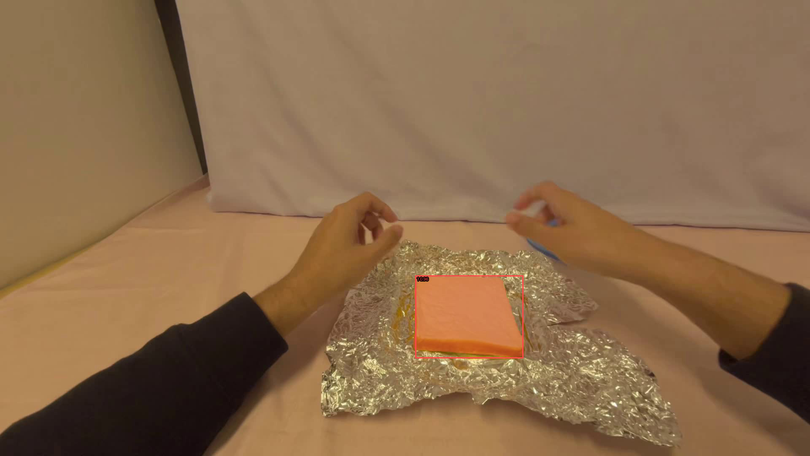
Recorded EgoDex query cropRecorded EgoDex future clip frame
Query at tFuture 4-s clip

Unwrap a chickenburger from foil

V / L / embodiment-native action
1,000 queries / 800 episodes
DROIDTraining-free ICL domain
Recorded DROID query cropRecorded DROID future clip frame
Query at tFuture 4-s clip

Move the maroon cloth to the left

V / L / embodiment-native action
1,000 queries / 800 episodes
LIBEROTraining-based ICL domain
Recorded LIBERO query cropRecorded LIBERO future clip frame
Query at tFuture 4-s clip

Put cream cheese and butter in the basket

V / L / embodiment-native action
1,000 queries / 800 episodes
RoboMIND–Franka-dualDual-arm real-robot coverage
Recorded RoboMIND Franka-dual query cropRecorded RoboMIND Franka-dual future clip frame
Query at tFuture 4-s clip

Close the drawer with the right arm

V / L / embodiment-native action
1,000 queries / 800 episodes

Shared-gallery evaluation

Current-state queries4,000 queries · 3,200 episodestext + SAM3 zoom + current action
Clip-levelunique positivethe uniquely paired future 4-s window
Episode-levelmultiple positivesany indexed window from the same source-scoped episode
The gallery spans all four sources. Ranking uses cosine similarity on L2-normalized embeddings without reranking; clip- and episode-level relevance are evaluated separately.
Inside the retrieval

Compare Robota-Embed, Gemini and Omni on a recorded DROID interaction.

Robota-Embed · step 26,275Raw cosine ranking16 sampled frames / 4 s

DROID retrieval comparison

04 · Embed2Evolve

Higher task success, with fewer policy tokens.

Embed2Evolve grows task-local context from experience and execution feedback, then freezes the selected harness for testing while GPT and embedding weights remain fixed.

Embedding-guided context evolution

Experience becomes task-local memory.

Eligible completed attempts populate task-local memory. The context harness evolves how the policy accesses that memory; it does not evolve policy weights. The selected harness improves final task success while reducing test-time policy context.

Method · Embed2Evolve

Develop the context. Freeze the best harness. Test fresh.

01 / DevelopmentMemory and context recipe evolve; policy and embedding weights stay fixed.
CollectCompleted rolloutsSuccesses and failures
IndexRobota-EmbedVision · text · native action
EvolveMemory M + recipe θHow to retrieve and use context
EvaluateSuccess · ticks · timeRepeat the development loop
SelectFreeze M* + θ*Best task-local harness
Selected memory + recipe carry into fresh final tests
02 / Frozen testingNo test-time memory or recipe evolution.
ObserveCurrent RGB + task + actionFresh test rollout
RetrieveUseful contextFrom frozen M* via θ*
DecideFixed GPT-6 AstraViews, state, own recent history
ExecuteEEF poses + gripperFixed controller; observe again
Task successAll final test rollouts
68%+44 pp vs. Direct
GPT-6 Astra Direct24%Embed2Evolve68%

Five selected ManiSkill simulation tasks with 20 fresh matched initializations per task and condition.

Policy tokens / rolloutAll final test rollouts
0.518M−43.7% vs. Direct
GPT-6 Astra Direct0.921MEmbed2Evolve0.518M

Means include successful and failed test rollouts; development rollouts are excluded.

Matched evolved harnessesSame protocol · independently evolve each context system
Evolve + Omni-Embed-Nemotron-3B33% success≈2.531M tokens / rollout
+35 pp task success−79.5% policy tokens
Shared-success efficiency19 matched initializations where both methods succeed
−64.1%policy decisions−41.4%observed client time1.90×mean task-wise time ratio

Success and token results include all final test rollouts. Decision and time comparisons use shared successes; observed client time includes API waits and caller/scheduling differences.

Five-task final evaluation

Five selected ManiSkill simulation tasks; 20 fresh matched initializations per task and condition.

TwoRobotStackCube-v1Direct 25%Random history 15%Embed2Evolve 85%

Task results use all final tests, including failures. Token means exclude development. Robota and Omni context systems evolve independently under the same protocol before freezing. Omni per-task token means were not reported.

05 · Embed2ICL

Retrieve context, then act.

Embed2ICL turns retrieved physical experience into the native conditioning interface of training-free and training-based robot policies.

Embedding-guided in-context learning

One retriever, two policy interfaces.

A training-free path initializes DreamZero's visual cache with a selected reference. A training-based path conditions Fast-WAM on cached Context Tokens from the retrieved demonstration.
47.0% → 56.3%DROID-Sim · 3-task mean86.4% → 92.8%LIBERO · 5-task difficult-subset mean

Robot query

VLA
Robota-Embed
Cosine retrieval Indexed experience
Two policy interfaces

Training-free

DROID top-kReranking Agent
Useful context
Early frame of the paper's selected DROID referenceLater frame of the same DROID reference
Recorded reference video
Visual KV cacheWarm-up
DreamZeroFrozen policy
Only the selected video initializes the cache; live observations update the rolling cache.

Training-based

EgoDexRecorded human reference used in the paper's training-based frameworkTop-1
Load cachedContext Tokens32 × 1024 tokens + context mask
PrefillingNative cross-attn.width adapter
Fast-WAMFine-tuned policy
Pick FruitTwo arms retrieve and place fruit into the center basket.
Mean normalized task progress · 12 rollouts / conditionNo ICL75.00%→Embed2ICL79.17%
Split CupOne hand stabilizes the stack while the other separates a cup.
Mean normalized task progress · 12 rollouts / conditionNo ICL66.67%→Embed2ICL87.50%

Technical report

Build robot context from physical experience.

Robota-Embed unifies vision, language, and native action for predictive experience retrieval, then applies the same representation to context evolution and robot in-context learning.
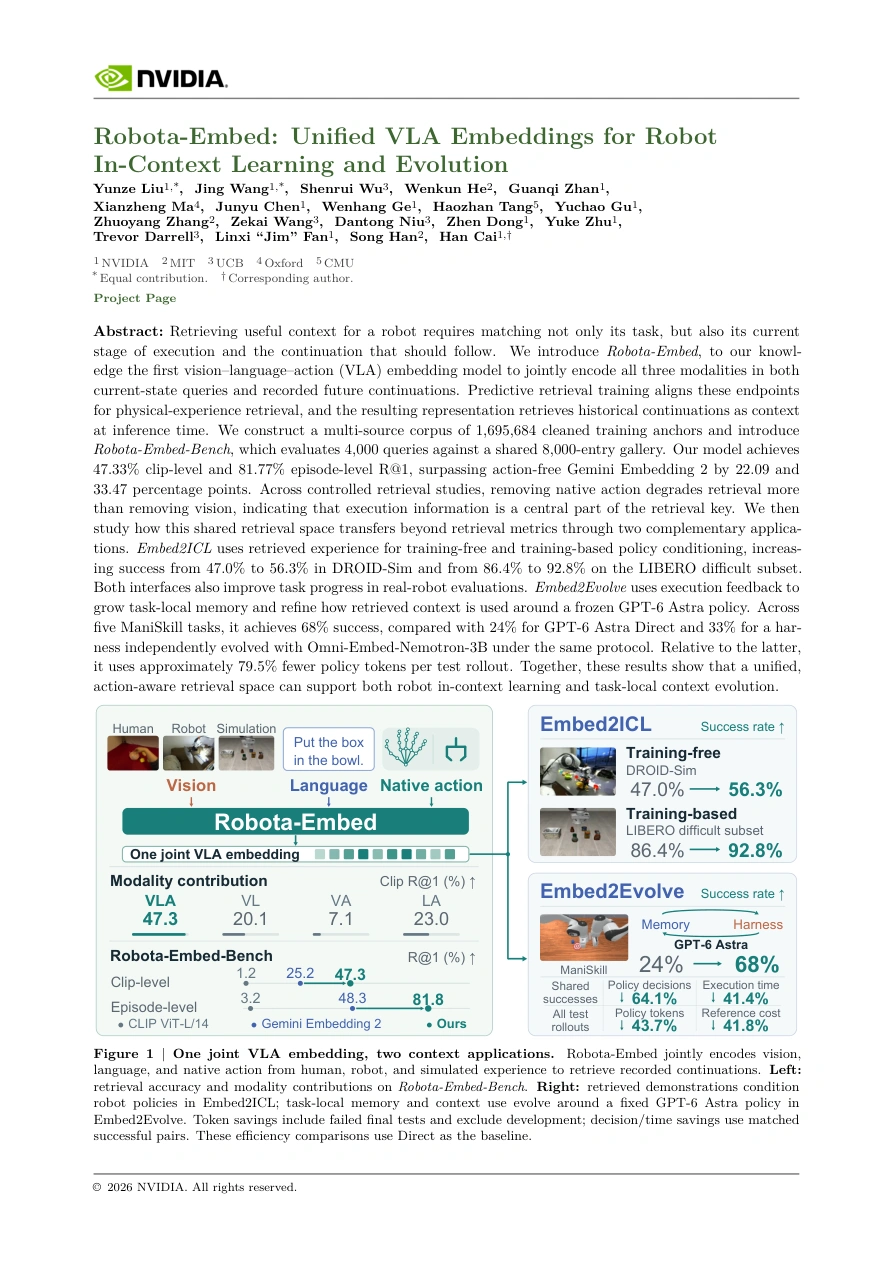
First page of the Robota-Embed technical report
Project resourcesReport availableRelease status

Technical report

The complete report, with methods, evaluation, and supplementary analysis.

Download PDF ↗

Code

Coming soon.

Model & benchmark

Coming soon.

Citation

Coming soon.

Robota-Embed